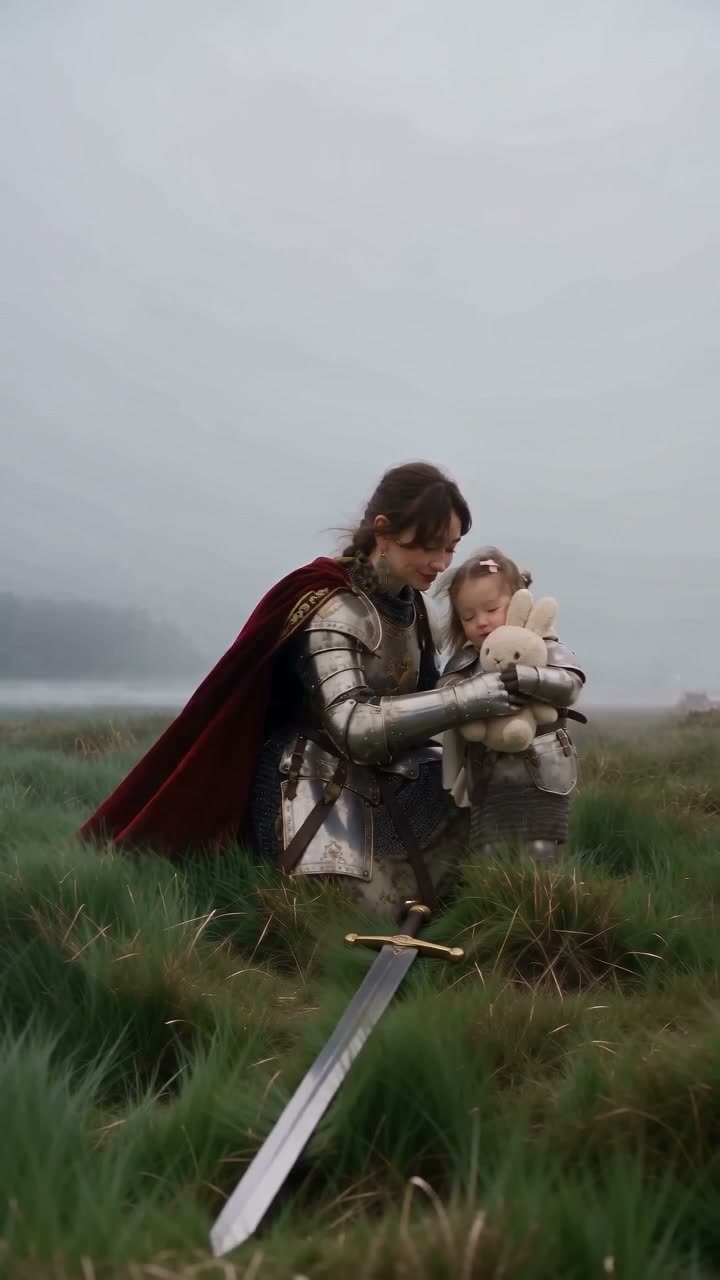
What happens in the knight sword swap video, shot by shot?
All versions share the same narrative, in one continuous scene:
| Beat | What you see | What you hear (Standard) |
|---|---|---|
| Opening | Your small knight stands alone in the wind wearing small silver armor and a short cape, eyes open against the wind, holding a sword twice their size. | Howling wind. |
| The walk-in | The tall knight from photo 2 walks through the fog and kneels beside the small one. | Armor clinks with each step. |
| The swap | The tall knight lifts the heavy sword and offers your object instead: a plush bunny, unless you select otherwise. | An original slow, gentle orchestral score. |
| The ending | The small knight holds the object with both arms, while the tall knight stands guard with the sword in the grass. | Wind and the score, with no lyrics or dialogue. |
The video includes original sound. You can disable it on the result screen and add your preferred sound when posting. Best is not offered on this page.
Red cape or Golden armor? The two references tell this narrative in two visual styles.
- Red cape follows the @gazizaaz clip. The tall knight wears silver plate armor and a long dark red cape. This is the default.
- Golden armor follows the @ray_chieee clip. The tall knight wears golden plate armor over chainmail and a long, sheer ivory cape with gold embroidery.
Red cape and Golden armor each make one video on this page.
| Reference | Standard (default) |
|---|---|
| Red cape | Seedance 2.5 takes your two photos (and object photo, if added) and creates the sword swap directly from them, with no intermediate AI picture, your two knights in silver armor, the tall one in a long dark red cape: 10 s, 720p, vertical 9:16, with original sound. It follows the narrative and style of the clip, not exact shots. |
| Golden armor | Smew AI first generates a photo of your two knights in golden armor with your object (Nano Banana 2.1), then Kling 3.0 animates the sword swap: 10 s, 1080p, vertical 9:16, with original sound. It follows the narrative and style of the clip, not exact shots. |
Why does Standard generate a new scene? The cheaper models that replicate a clip shot by shot (Seedance 2.0 Mini, Seedance 2.5 and Kling O3) frequently kept the original mom and child instead of the people in photos. Only Genjutsu swapped both faces consistently. So Best replicates the clip with Genjutsu, and Standard builds the same narrative from your photos.
Both versions are vertical clips with sound, ready to post. Best is not offered on this page.
We tested the references on 8 October 2026 and Red cape Standard on 12 and 13 October 2026, with AI-generated photos. On 13 October Red cape Standard shifted to Seedance 2.5 directly from photos: in our face check the faces matched photos much more closely than with the photo-first method. Faces and pets transferred well, and the object appeared large and clear. Most Standard runs look great, though occasionally a face resembles the photo less, or the original clip's style shows through. If that happens, run again. Results vary each time.
To select a reference, press "Create your own" and choose Red cape or Golden armor, or press the button under an example on this page.