Choosin' Texas emo version: Take the rooftop emo-singer role

Put your face into an emphatic rooftop singing performance. One portrait becomes the lead in a nighttime scene driven by big gestures, a rock-style vocal delivery and the reference clip’s pacing.

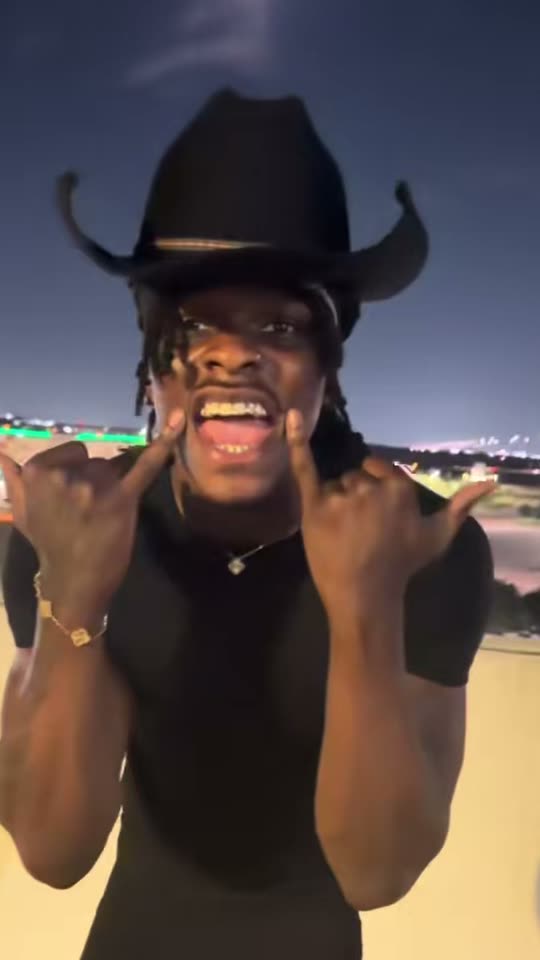
The original Choosin' Texas Emo AI reel by @kobbapotOriginal reel
  • 1 photo you add
  • 20 s video
  • No prompt to write
  • No watermark

No prompt to write: Add your photo and tap once

Create your own

Ready in a few minutes · From 304 credits

A country song becomes a rooftop rock meltdown. The Choosin' Texas emo format borrows the dramatic body language of an overcommitted cover performance: rock gestures, pleading hands, deep bounces and a final drop to one knee. The comedy is the conviction, with a parking-garage roof supplying a wonderfully unlikely stage.

Smew creates a 20-second AI take with the consenting adult in your photo as the performer. The configured emo-cover soundtrack is added after the picture is generated. You do not need to sing, record your voice or visit a rooftop; a clear portrait with enough body and clothing visible supplies the personal part of the scene.

Example

A closer look at Choosin' Texas emo version

Visual references for the format, not Smew customer results. Your generation can change fine details, expressions and movement.

Visual reference

A visual reference, not a Smew customer result. Your generated details will differ.

Use this reference
Step by step

Make your Choosin' Texas Emo AI video

Choose a version, add the required photos and check the displayed credits before generating.

  1. Add the rooftop performer

    Upload one clear adult waist-up or full-body photo. Show the hair and outfit you want represented. If a cowboy hat is part of your intended look, include it in the photo rather than assuming the reference costume is an automatic requirement.

  2. Review the longer cover take

    The current choice is Seedance 2.5, 304 credits, 20 seconds, 720p and vertical 9:16. The gestures, scene and audio reference are configured. No singing upload or prompt-writing step is required.

  3. Listen and watch before sharing

    Follow the task on Dashboard. Library uses the finished file after the soundtrack has been joined. Inspect the camera lunges, face, hands and kneeling finish, remembering that the singing is the reference cover rather than a new recording of your voice.

Choose a photo that keeps the subject recognizable

Choose one consenting adult aged 18 or over, facing the camera in even light. A waist-up or full-body image provides more body and outfit information than a tightly cropped selfie. The performance includes bends, lunges and a kneeling ending, so visible proportions are useful even though you do not need to copy those poses yourself.

Hair and clothes should be clear. The intention is to preserve the uploaded person's appearance rather than automatically add the reference performer's hat, long hairstyle or boots. If you want a similar dark stage look, wear it in the source photograph. Hidden hair and a face under a hat shadow are less useful than a clear view.

Avoid sunglasses, a mask, a strong face filter and any second person. There is one adult role and no pet choice. A safe photograph taken at home is sufficient; the apparent nighttime rooftop performance is generated.

Where the format comes from

The source context connects the format to Ella Langley's Choosin' Texas and a wave of rock or emo reinterpretations. @piratemike311's June 2026 post supplies one earlier cover example. The specific rooftop performance referenced here is @kobbapot's September 29 post, which turns the song into a highly theatrical phone-camera solo.

Later duets, rooftop variations and the creator's remix roundup show how the performance became a reusable joke. Country styling and emo-rock gestures meet in a deliberately exaggerated delivery. That specific visual is different from a studio band cover or a dance challenge that merely uses the same song.

Smew credits the reference performance as background and generates a separate personalized take. It is not connected with the singer, cover performer or their labels. No changing view count or claim of a first-ever AI version is needed to explain the format: the roof, gestures and committed finish identify it.

  1. An earlier emo cover illustrates the song's genre-switching context. Credited example

  2. The credited rooftop performance combines country styling with exaggerated emo delivery. Credited example

  3. A duet shows an early response to the rooftop version. Credited example

  4. The creator revisits the cover in a remix roundup. Credited example

  5. Another rooftop interpretation changes the costume while retaining the performance idea. Credited example

  6. Photo-based AI templates offer another way to reinterpret the rooftop scene.

Copy and paste

What the built-in recipe controls

These instructions are included in the template. Your uploads provide the identities; the selected version controls the scene and movement.

You

1 photo: you (18+), face clear, from the waist up or full bodySeedance 2.520 s · 720p · 9:16304 credits
Video prompt

Use [Video 1] for a single handheld twenty-second rooftop performance, retaining the low cream parking-garage wall, distant city lights and dark sky. Match the opening wall-supported squat and spring, the close hands-near-face emphasis during 1–4 s, the pleading sideways turn through 7 s and the wall-gripping bounces through 12 s. Continue with crossed arms and chest gestures through 14.5 s, the lunge and low camera follow through 17 s, then the final kneeling performance toward the floor. Reproduce mouth and jaw shapes from the reference, not newly written lyrics. Replace the lead performer with the adult in [Image 1], keeping their own face, hair and clothes. Keep assigned human faces individually recognizable: preserve facial structure, complexion, eye and hair coloring, age, and characteristic accessories through movement. Use the source hairstyle and clothing unless this scene explicitly changes them. Keep bodies coherent and identities attached to their own roles. Keep every emotional beat as a physical performance; do not request a known artist’s identity or vocal imitation. Keep performance and mouth timing aligned with the reference, but produce no new lyrics, vocals or known song recording. The soundtrack is added after generation. Avoid unintended duplicates, fused bodies, extra limbs, captions, logos, watermarks and visible interface elements.

1382 characters

Models, duration and credit cost

You pay in credits. The Generate button shows this price before you spend anything. These are the options on this page.

OptionModelWhat you getCredits
YouSeedance 2.520 s · 720p · 9:16304

One-time packs and plans are on the pricing page. A failed video gives its credits back.

The emotional arc of the rooftop cover

The performance starts low against the wall, with the body bouncing before a quick move toward the phone. Raised hands and rock gestures announce a much bigger emotional response than the ordinary rooftop setting suggests. Pleading hands and a sideways turn then change the mood without losing the exaggerated commitment.

The middle alternates wall-backed bounces, thrown-back head movements and gestures toward the chest. A lunge near the camera makes the identity more visible, but also makes this a demanding moment for generated motion. The final descent to one knee provides a clear ending rather than letting the scene stop in the middle of a gesture.

Smew follows that broad 20-second performance structure in vertical 9:16. The roof, city-night atmosphere and handheld feel belong to the scene, while your upload guides the performer. Fine gestures, mouth motion and framing can vary between takes. Expect a personalized interpretation of the cover, not an exact replacement that preserves every source pixel or guarantees perfect singing synchronization.

What the one-photo workflow supplies

The template's single adult slot controls the intended lead. It does not create a duet, cast a backing band or place the original artist beside you. The uploaded face, hair and clothing provide identity cues while the saved recipe supplies the wall, roof, gestures and dramatic physical arc.

The current output is 20 seconds at 720p, vertical 9:16, using Seedance 2.5 for 304 credits. The reference emo vocal is handled after picture generation and saved in the completed file. No microphone recording is requested from you, and the system is not cloning your actual singing voice.

A browser workflow removes the need to assemble the performance manually, but it does not remove review. Watch the face when the character approaches the lens, the knees at the ending and the hands around the chest and head. The reference footage on this page explains the target mood and is credited accordingly; it is not a promise that every customer result will reproduce the same motion exactly.

When the rooftop take loses resemblance

A cowboy hat or reference-like hairstyle can appear when the upload leaves those details ambiguous. Choose a photograph where your own hair and outfit are visible. A close selfie gives strong face information but little evidence for the full-body clothing and kneeling pose, which can make the performance stiff or overly influenced by the reference.

The lunge and fast camera motion may blur the face even if a still opening looks accurate. Check that the identity recovers after movement rather than judging one blurry frame in isolation. Hands raised near the face and crossed at the chest can also introduce artifacts.

The vocal is a configured reference recording, not a fresh performance by the generated person. Mouth motion may not match every syllable. A different take can vary, but another generation is not a guaranteed lip-sync repair. Improve an unsuitable source photograph first, then decide whether the overall delivery works as a clearly labeled fictional cover scene.

Credit the cover and give your own setup

The song's authorship and the cover performance are separate parts of the reference. When discussing the source, credit Ella Langley's song and @kobbapot's rooftop interpretation. A generated version with that soundtrack does not transfer either set of rights or establish permission for every advertising or commercial use.

A caption can explain that the country song has become your rooftop rock moment, or that a routine evening suddenly turned into a dramatic concert. Write your own setup instead of copying lyrics. The visual already supplies the theatrical energy, so a simple sentence usually gives viewers enough context.

Keep the AI disclosure and the subject's consent. If you post through a platform with licensed music choices, check how those permissions apply to an embedded audio recording. Descriptive song and emo-cover tags can identify the format, but they do not guarantee reach, and the clip should not be presented as an official performance or collaboration.
FAQ

Choosin' Texas Emo AI questions

What is the Choosin' Texas emo version trend?

It is the theatrical rooftop interpretation of a country song, associated with @kobbapot's phone-camera cover. Rock gestures, deep bounces and a kneeling finish turn the performance into a comic emotional event. Smew creates an AI take with your uploaded adult as the lead, rather than making a new studio recording of the song.

How do I make the Choosin' Texas emo version AI video?

Add one clear adult waist-up or full-body image, review the 304-credit choice and start generation. The current result is 20 seconds at 720p in vertical 9:16. The performance recipe and configured soundtrack are included. Track it from Dashboard and review the completed file in Library.

Is the original reel AI?

The reference is presented as the creator's filmed performance and is credited for that reason. It illustrates the gestures and setting, not a Smew customer generation. Your personalized result is AI-made. Keep that distinction when describing the source or sharing the new take.

Do I have to sing?

No. You supply a photograph, not a vocal recording. The configured reference cover audio is joined after picture generation. That means the singing is not your cloned voice or evidence that you performed the cover. Mouth timing can vary, so review the full audiovisual result.

Do I get the cowboy hat?

The intention is to use your own hair and clothes rather than require the reference costume. Include a hat in your photo if it is part of your desired appearance. Generated details can still vary, especially when hair or clothing is hidden. A scene reference is not a guaranteed costume transfer.

Is this the choosin texas guy version tiktok people talk about?

If you mean the nighttime phone-camera cover with emphatic rock gestures and a cowboy-style look, that is the referenced format. Other Choosin' Texas clips may be dances, band recordings or unrelated parodies. Compare the setting and performance rather than assuming the song title identifies one universal template.

Is it the same as a choosin texas rock version?

No. A band arrangement or full rock cover is a musical work, while this page follows one short rooftop-performance scene. The current template does not compose a new arrangement, generate a whole song or cast a band. It uses the configured cover soundtrack with a personalized visual take.

Is Ella Langley in my video?

The intended performer is the adult from your photo. The song connects the trend to its artist, but the template is not an official music video or endorsement. Use an image you are entitled to provide rather than a celebrity photograph. The reference soundtrack remains subject to its owners' rights.

Can a woman sing it?

Yes. The role uses a consenting adult identity rather than requiring a man who resembles the reference. A clear photograph showing face, hair and outfit helps the model interpret the performance with your appearance. Review movement and clothing in the finished take because exact body details are not guaranteed.

Can I make it with my pet?

There is no pet choice in the current catalog for this template. It has one adult photo slot. Do not assume that an animal upload is supported because another trend has a pet mode. Choose a template with an explicit pet recipe if you want an animal-centered performance.

What do I need to sing choosin texas with your photo?

Use one sharp adult portrait with the face toward the camera and preferably the waist or full body visible. The current output is 20 seconds, vertical 9:16 at 720p, with the configured emo-cover soundtrack. Processing time varies; Dashboard reports the task while it runs.

Try Choosin' Texas Emo AI with your photos

Choose your version, review its output and credits, then start your own take.

No watermark. A failed video gives its credits back. Secure checkout by Stripe.